Putting Forward Deployed on the Org Chart Doesn't Make You Forward Deployed
AI is collapsing the distance between customers, product, and engineering. The services firms and procurement systems built around labor scale have a much harder transformation ahead.
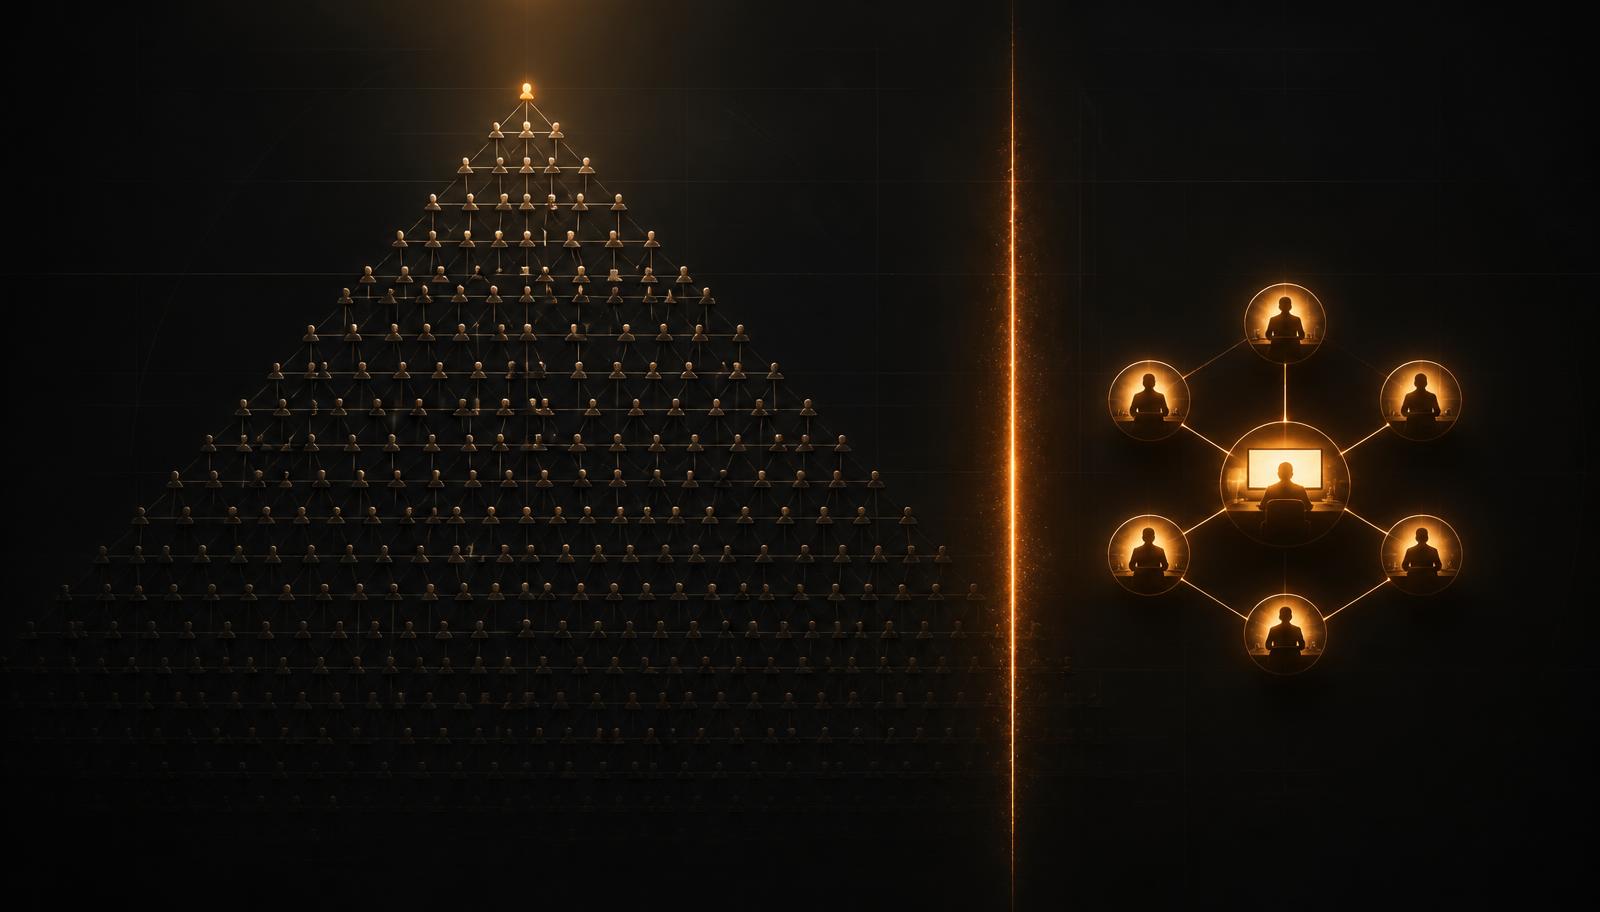
Something strange is happening inside enterprise technology. Almost overnight, everyone has discovered Forward Deployed Engineering. New FDE practices are being announced, new titles are appearing, AI studios are opening, and existing engineering organizations are being recast as customer-embedded, AI-enabled, and forward deployed.
Some of that transformation is real. Some of it looks suspiciously like the same delivery pyramid with a much better job title. Because Forward Deployed Engineering isn't about where the engineer sits. It's about how little organization sits between the engineer and the problem.
That distinction matters because AI isn't simply making the existing enterprise development process faster. It is beginning to change the process itself.
For decades, enterprise technology followed a fairly predictable sequence: business need, requirements, specification, SOW, vendor, delivery team, software, customer acceptance. Then we optimized the labor underneath it. Keep expensive architects, product leaders, and program managers close to the customer. Move repeatable engineering work to lower-cost locations. Build enormous delivery centers, standardize roles, negotiate rate cards, and measure utilization. It became an extraordinarily effective industrial system for producing software, and it created some of the largest technology services companies in the world.
But the underlying assumption was that software was expensive to produce and that output scaled, at least roughly, with labor. AI is attacking both assumptions at once. The important question is rapidly becoming less how cheaply can we staff this specification? and more how quickly can we figure out what actually works? Those sound like two versions of the same question. They aren't, and they produce completely different organizations.
Why spend three months specifying something you can discover in three weeks?
Traditional enterprise development made economic sense because thinking was relatively cheap and building was expensive. If implementing an idea required 40 engineers, twelve months, and several million dollars, spending months defining exactly what those engineers should build was rational. Changing direction halfway through was expensive, so enterprises tried to eliminate uncertainty before development began: requirements workshops, architecture documents, functional specifications, RFPs, statements of work, steering committees, and then, eventually, software.
AI changes that calculation. When a small, experienced team can turn an idea into a credible working prototype in days or weeks, the economics begin to invert. Why spend twelve weeks debating what customers might want when you can build enough in two weeks to ask them?
That doesn't mean requirements disappear. Security requirements matter, regulatory requirements matter, architecture matters, data governance matters, and integration constraints matter. But product requirements increasingly become hypotheses rather than instructions. We believe this workflow matters, so build enough to test it, put it in front of ten customers, watch what happens, change it, and put it back in front of them. The working product itself becomes part of the requirements process.
The customer is moving inside the development loop
This may be one of the most underappreciated consequences of AI-assisted development. For years, we talked about agile development while maintaining surprisingly long distances between the people building software and the people using it. Product managers interviewed customers, business analysts documented requirements, engineering received stories, developers implemented them, QA validated them, and eventually the customer saw the result.
AI makes that separation increasingly unnecessary. A product manager and a handful of senior engineers can sit with a customer cohort, understand a problem Monday, have something working Wednesday, watch customers use it Thursday, and change direction Friday. That's not merely faster software development; it is a different method of discovering products.
The organization gets more learning cycles per unit of time, and those cycles compound. A team that completes ten meaningful customer-feedback loops while another completes one doesn't simply move ten times faster. By the tenth cycle, it possesses information the slower organization hasn't discovered yet. Velocity creates knowledge, which makes velocity an economic advantage rather than an engineering vanity metric.
The market is already telling us something
You don't have to look very hard to see the organizational response. OpenAI launched an entire Deployment Company in 2026 built around embedding forward deployed engineers into organizations working on difficult problems. The premise is not simply to advise customers about AI, but to put specialized engineers alongside them to build and deploy systems in their actual operating environments.
AWS went further. In 2026 it announced a dedicated Forward Deployed Engineering organization backed by a $1 billion investment, describing the demand rather plainly: customers need experienced AI engineers working directly with their teams. Its stated objective is to compress deployment timelines from months to days and leave customers capable of operating what was built.
IBM Consulting has made perhaps the most interesting admission of all. In describing its Forward Deployed Units, IBM wrote that "for thirty years, labor was the scaling factor for delivery." More humans meant more output. Time and materials, FTE pricing, team sizing, utilization, and much of the commercial machinery surrounding technology services evolved around that assumption. IBM then acknowledged that most enterprise delivery models—including its own—remain calibrated to that world. AI changes the scaling factor, and IBM says its new model can allow a six-person pod, supported by specialized AI agents, to perform work that previously required a 30-person team. That is not incremental productivity. That changes the economics of the services industry.
The thousand-person bench isn't the flex it used to be
For years, one of the most reassuring things an enterprise technology provider could say was some version of we have 5,000 Java developers, we have delivery centers around the world, and we can add another 200 people to your program next quarter. Scale signaled safety, and for large classes of technology work it still does.
But for new product development, AI, and automation, that sales pitch is beginning to sound different, because the scarce resource increasingly isn't access to another hundred developers. It's access to six people who deeply understand the problem and are capable of making very good decisions very quickly. A senior engineer who understands the customer, architecture, data, domain, and available AI tooling has extraordinary leverage. Put that engineer beside an equally strong product person, designer, domain expert, and a few other senior engineers, and something interesting happens: you don't just reduce headcount, you eliminate communication paths. Handoffs disappear, context stays inside the team, decisions happen immediately, and customers speak directly to the people creating the product. AI handles increasing amounts of the mechanical work required to turn those decisions into software, so the organization gets smaller while its delivery capacity increases.
Putting "Forward Deployed" on the org chart doesn't make you forward deployed
Naturally, the traditional services industry sees this happening, and suddenly everyone has discovered Forward Deployed Engineering. There are new FDE practices, new job titles, new AI studios, and new deployment units, with thousands of existing engineers being described as AI-enabled, customer-embedded, and forward deployed. Some of that transformation is absolutely real. Some of it looks suspiciously like the old delivery model with a much better job title.
There is an important distinction. Forward Deployed Engineering isn't an engineer who happens to work at the customer's office; it is an operating model. A genuine forward-deployed team is small enough that everyone understands the problem, senior enough to make decisions, technical enough to build the solution themselves, close enough to the customer to watch the problem occur, and empowered enough to change direction without sending a requirement through five layers of delivery management.
If the forward deployed engineer discovers something Monday but needs a product owner, solution architect, delivery manager, offshore lead, change-control process, and steering committee before someone changes the software, you haven't created Forward Deployed Engineering. You've forward-deployed the front end of the waterfall. The title isn't the innovation; removing the organizational distance is.
Wednesday: working change in the customer's environment.
Friday: direction adjusted from observed use.
Then: product owner, solution architect, delivery manager, offshore lead, change control, steering committee.
Eventually: a change ships.
The services pyramid has an AI problem
The traditional services pyramid wasn't a mistake. It was brilliant economic engineering: put a small number of experienced, expensive people at the top, put increasingly large numbers of lower-cost people underneath them, move execution into lower-cost labor markets, standardize the work, increase utilization, and add people as demand increases. Revenue scales with headcount, the customer gets labor arbitrage, and the provider gets leverage.
AI introduces an uncomfortable possibility. What if six exceptional people can increasingly accomplish what once required 30? That's wonderful for the customer. It is less obviously wonderful for a business whose revenue depends on billing the other 24. IBM describes the problem particularly well: organizations that fail to change the commercial model risk allowing the AI productivity dividend to become fewer billable hours rather than captured value from increased output.
That is why deploying AI coding tools to 100,000 consultants does not, by itself, make a services company AI-native. It might simply create a more productive version of the old services company. The difficult transformation isn't technological. It's economic, and it begins the moment customers stop wanting the pyramid.
Offshore isn't dead. Its job is changing.
This is where the conversation can get oversimplified. AI doesn't mean offshore technology delivery disappears. The world's existing technology estate is enormous: banks, manufacturers, retailers, governments, airlines, and healthcare organizations operate decades of accumulated software that someone has to run, maintain, patch, upgrade, integrate, secure, keep compliant, and eventually consolidate, migrate, or retire. There is an enormous amount of keep-the-lights-on work, AI will make those teams more productive too, and large global delivery organizations are exceptionally good at industrialized technology operations.
So the emerging split may not be onshore wins and offshore loses. It may be that maintenance industrializes while innovation compresses. KTLO moves toward the most cost-efficient, automated, globally distributed operating model capable of safely maintaining the existing estate, while strategic development moves toward smaller, senior, AI-amplified teams sitting extremely close to the business and its customers. The enterprise technology organization becomes a barbell: enormous efficiency maintaining yesterday on one end, tiny teams disproportionately responsible for tomorrow on the other. The uncomfortable place is the middle, and the middle is where a lot of traditional services revenue currently lives.
Then there's procurement
This is where the transformation collides with another system designed for the labor era. Enterprise procurement became extraordinarily good at buying external technology labor and services at scale. SAP Fieldglass is a useful example—not because there's anything wrong with Fieldglass, but because its services-procurement model illustrates the assumptions perfectly. Fieldglass supports statements of work that define scope, timelines, deliverables, costs, worker roles, and milestones, and buyers can distribute SOW bids to multiple suppliers and compare responses by cost, duration, location, and the number and type of workers. For known work, that is excellent governance.
Now imagine the emerging engagement. We have an important business problem. We don't know exactly what the solution should be. Give us six exceptional product and engineering people, put them beside our customers and business owners, give them access to the systems and data, and in 30 days we'll know dramatically more than we know today. Try putting that into a procurement process optimized around predetermined roles, rates, deliverables, and supplier comparisons.
The problem isn't Fieldglass. The problem is that the procurement philosophy surrounding systems like it often assumes the work can be specified before the most valuable learning has occurred. That creates increasingly strange outcomes. A six-person specialist company may be capable of producing a working prototype before an enterprise can finish qualifying it as a supplier. The supplier with the best six engineers can lose to the supplier with the largest approved bench. A small team proposing an iterative engagement can appear risky while a supplier confidently estimating a twelve-month project against unvalidated assumptions appears safe. And a $250-per-hour engineer can look five times more expensive than a $50-per-hour engineer even when the first produces a dramatically cheaper outcome.
The $250 engineer may be cheaper than the $50 engineer
This is where traditional rate-card economics begin to break down. Suppose one team costs $250 per hour per person and another costs $50. The procurement spreadsheet sees a 5x difference. But suppose the first team requires six people and the second requires 30. Suppose the first gets a meaningful product in front of customers in six weeks while the second spends three months moving from requirements through architecture into development. Suppose the first discovers during week three that a major assumption is wrong, and the second discovers it during user acceptance testing nine months later. Which team is cheaper? The hourly rate tells us almost nothing, because we're measuring the wrong arbitrage.
For twenty years, technology services competed heavily on labor arbitrage. AI creates another opportunity: velocity arbitrage. How quickly can we turn uncertainty into knowledge, turn knowledge into software, put that software in front of customers, discover that we're wrong, and change direction cheaply? Those questions matter because waiting has a cost. Every month before customers touch the product is a month without information. The fastest team isn't simply producing software sooner; it is learning sooner, and learning compounds.
Coding is getting cheaper. Knowing what to build isn't.
This may be the most important economic consequence of AI development. AI is aggressively reducing the cost of turning decisions into software. But AI doesn't automatically know which enterprise problem matters, which customer behavior should change the product, which seemingly insignificant workflow is actually mission critical, or which ugly 20-year-old system contains the data everyone needs. It doesn't inherently understand the political, regulatory, or operational constraints that determine whether a technically elegant solution survives contact with the enterprise.
Those are context problems, judgment problems, customer problems, architecture problems, and product problems. Something counterintuitive happens as implementation gets cheaper: the people closest to the problem become more valuable, not less. That's why product management is moving closer to engineering, why engineers are increasingly entering customer conversations, why customer cohorts are moving into the development process instead of appearing at the end, why rapid prototyping is becoming expected rather than exceptional, and why the forward-deployed model is attracting so much attention.
Procurement has a new job
None of this means enterprises should abandon procurement discipline. Quite the opposite: when creating software becomes easier, governance becomes more important. Security, privacy, financial controls, vendor risk, architecture, and regulatory compliance all matter more, not less. But enterprises need another lane for buying innovation—a way to procure small expert teams, 30-day discovery-and-build engagements, rapid prototypes, forward-deployed engineering, customer-cohort development, iterative SOWs, and outcome-oriented programs where discovering the precise solution is explicitly part of the work.
The traditional system protects enterprises from paying too much for technology labor. The emerging system also needs to protect them from something potentially more expensive: moving too slowly to exploit technology leverage. Those are different jobs.
The new services company sells learning speed
For decades, the great technology services companies built economies of labor. The next generation will build economies of expertise. Their advantage won't primarily be the number of engineers they employ; it will be the density of capability they can put against a problem. Their product people won't throw requirements over a wall to engineering, their engineers won't be separated from customers by account teams and business analysts, and their prototypes won't be demonstrations created after months of planning. They will be instruments for figuring out what should exist. And AI won't be a practice sitting somewhere inside the company; it will be embedded in how every person works.
The traditional services company sold capacity. The emerging services company sells something different: the speed at which an enterprise can turn uncertainty into working capability. That changes how teams are built, how software is developed, what onshore and offshore are best used for, what a great engineer is worth, what a services company should charge for, and eventually how enterprises buy technology.
For twenty years, technology leaders became extraordinarily good at asking how cheaply they could produce software. AI is forcing a better question: how quickly can we discover the right thing to build? Because putting "Forward Deployed" on an org chart is easy. Actually becoming forward deployed means dismantling some of the organizational machinery that made the old services model successful, and that's the harder transformation. The new labor arbitrage isn't geography. It's velocity.
Sources
- OpenAI, OpenAI launches the OpenAI Deployment Company to help businesses build around intelligence, May 2026.
- AWS, Introducing Forward Deployed Engineering for Partners: Winning the Future of Enterprise AI, June 2026.
- AWS, AWS invests $1 billion in forward deployed AI engineers, July 2026.
- IBM Consulting, Forward deployed units: IBM Consulting's field model for scaling AI and transformation, June 2026.
- IBM, A New Way to Make AI Actually Work in the Real World, May 2026.
- SAP, SAP Fieldglass Services Procurement and SAP Fieldglass SOW/SOW Bid documentation.